正在打开每日关注
Prime Agent:Harness如何放大模型能力
Prime Agent借助工具调用、多智能体协作与自我改进,把Opus 5得分从30.2%提升至95.5%。
来源摘录
Prime Intellect achieved HGI. Harness General Intelligence Prime agent raises Opus 5’s ARC-AGI-3 score from 30.2% to 95.5%. Uses: 1. RLM-native tool calling 2. Multi-agent orchestration 3. A self-improving harness Cannot WAIT to dive into this. https://t.co/tvfVOzBzMX
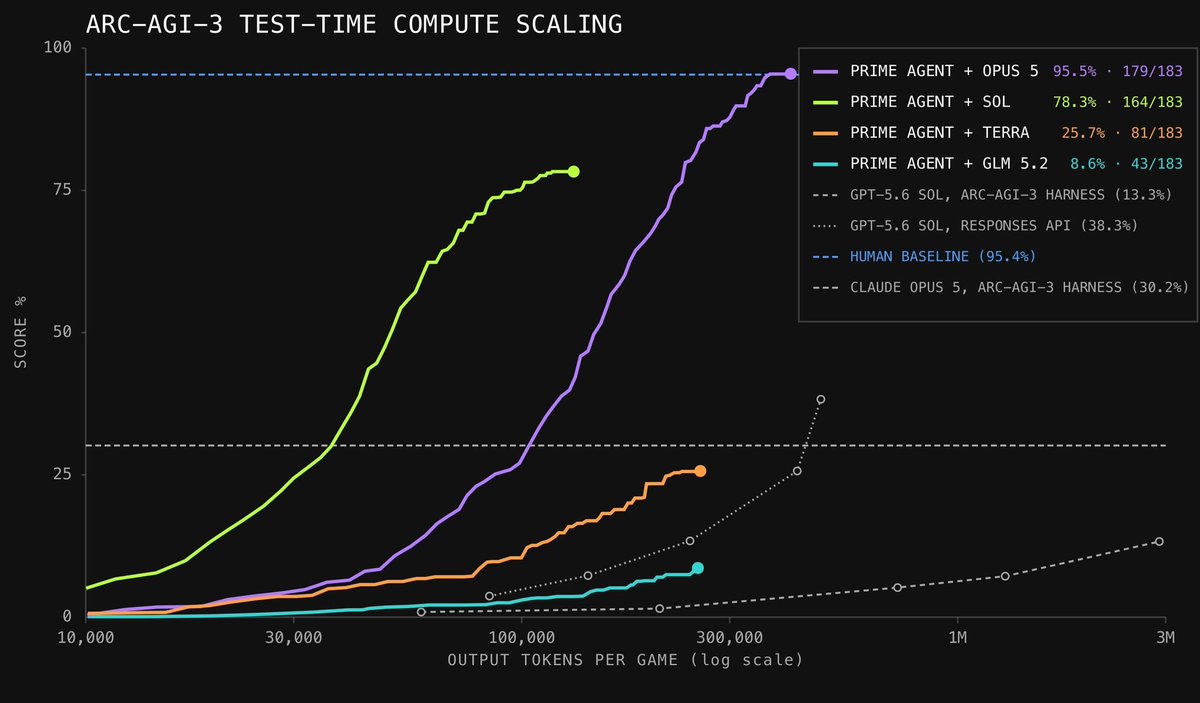
Prime Agent is a general-purpose coding harness On ARC-AGI-3, it scores 95.5%, surpassing the human-expert baseline, but the gain is not benchmark-specific. We see major improvements across models when compared to their proprietary harnesses: https://t.co/Xa8zZiDtbF
深度解析
是什么 这是一条关于 Prime Agent 的工程观察:它被定位为通用编码 harness,而非新的基础模型。推文宣称,同一个 Claude Opus 5 在 Prime Agent 中的 ARC-AGI-3 得分由 30.2% 提升到 95.5%,并超过 95.4% 的人类专家基线。图表还展示了 SOL、TERRA、GLM 5.2 等模型在不同输出 token 预算下的表现。
核心设计 价值主要来自运行时系统:RLM-native 工具调用让模型能更灵活地执行外部操作,多智能体编排负责拆解和协作,自我改进 harness 则持续调整任务策略。横轴采用每局输出 token 的对数尺度,说明性能提升与测试时搜索、迭代和计算投入相关,而不只是模型参数规模。
关键洞察 评估对象应从“模型本身”扩展为“模型+harness+接口+预算”的完整系统。harness 可能成为独立的能力放大层,甚至形成新的训练数据和训练目标。
边界与风险 这仍是项目方及转述者的宣传性结论,缺少完整方法、消融实验、成本延迟、可复现脚本和第三方验证。95.5% 也不能直接等同于通用智能;输出 token 增加可能带来显著成本与延迟,跨任务泛化仍需独立测试。